One Request, End to End: Tokenize, Prefill, Decode, Stream
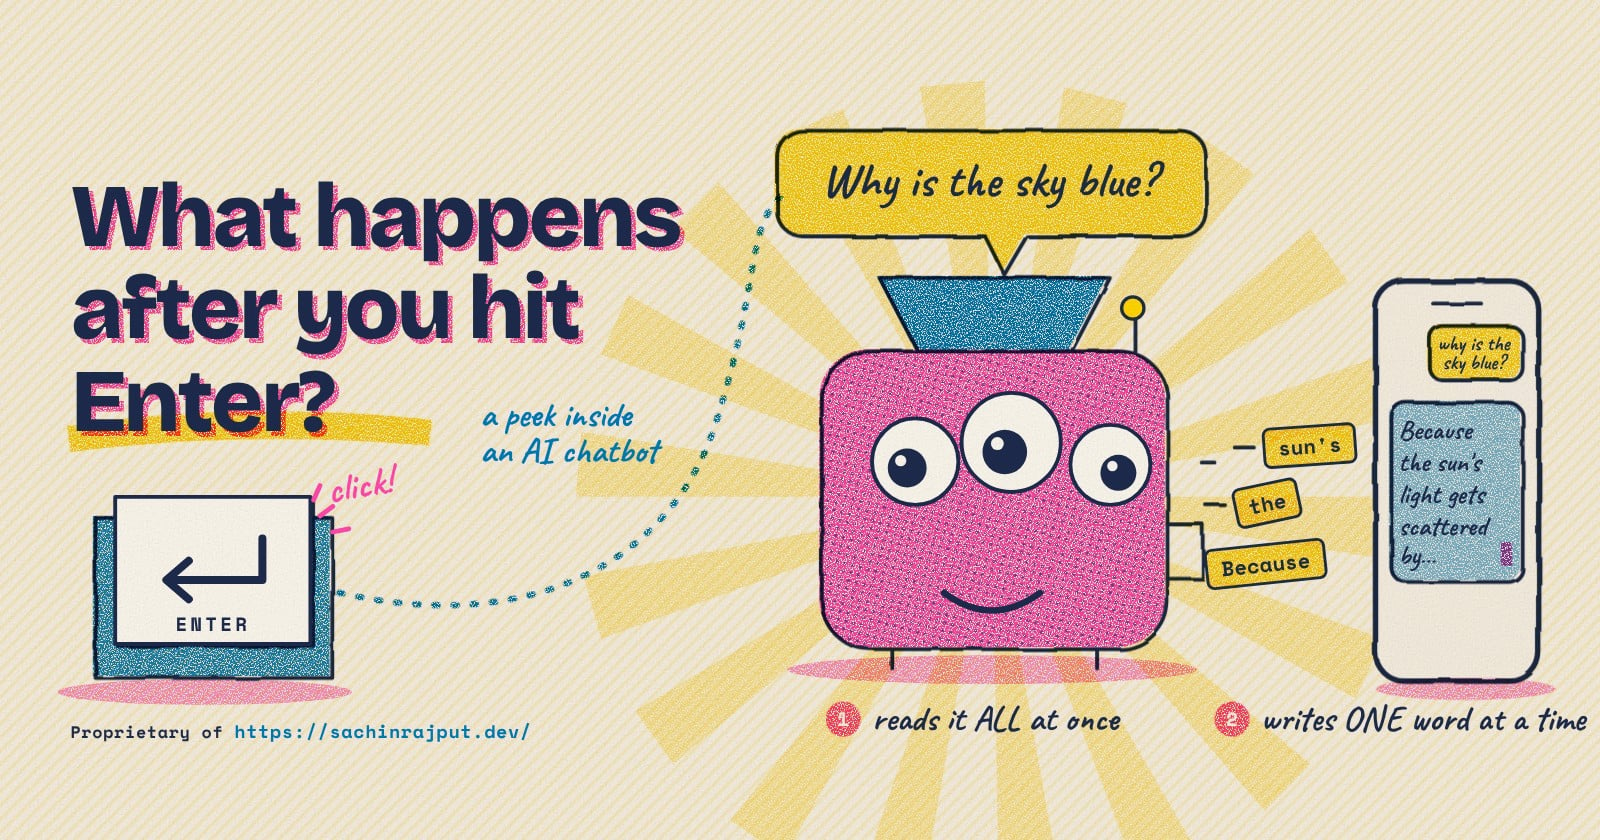
What really happens in the second after you ask a chatbot a question? A trip through the Word Factory, explained simply.
Series
How AI chatbots actually answer you, explained simply and measured for real. Short, friendly on-ramps to LLM inference: tokens, prefill, decode, the KV cache, batching and more.
What really happens in the second after you ask a chatbot a question? A trip through the Word Factory, explained simply.
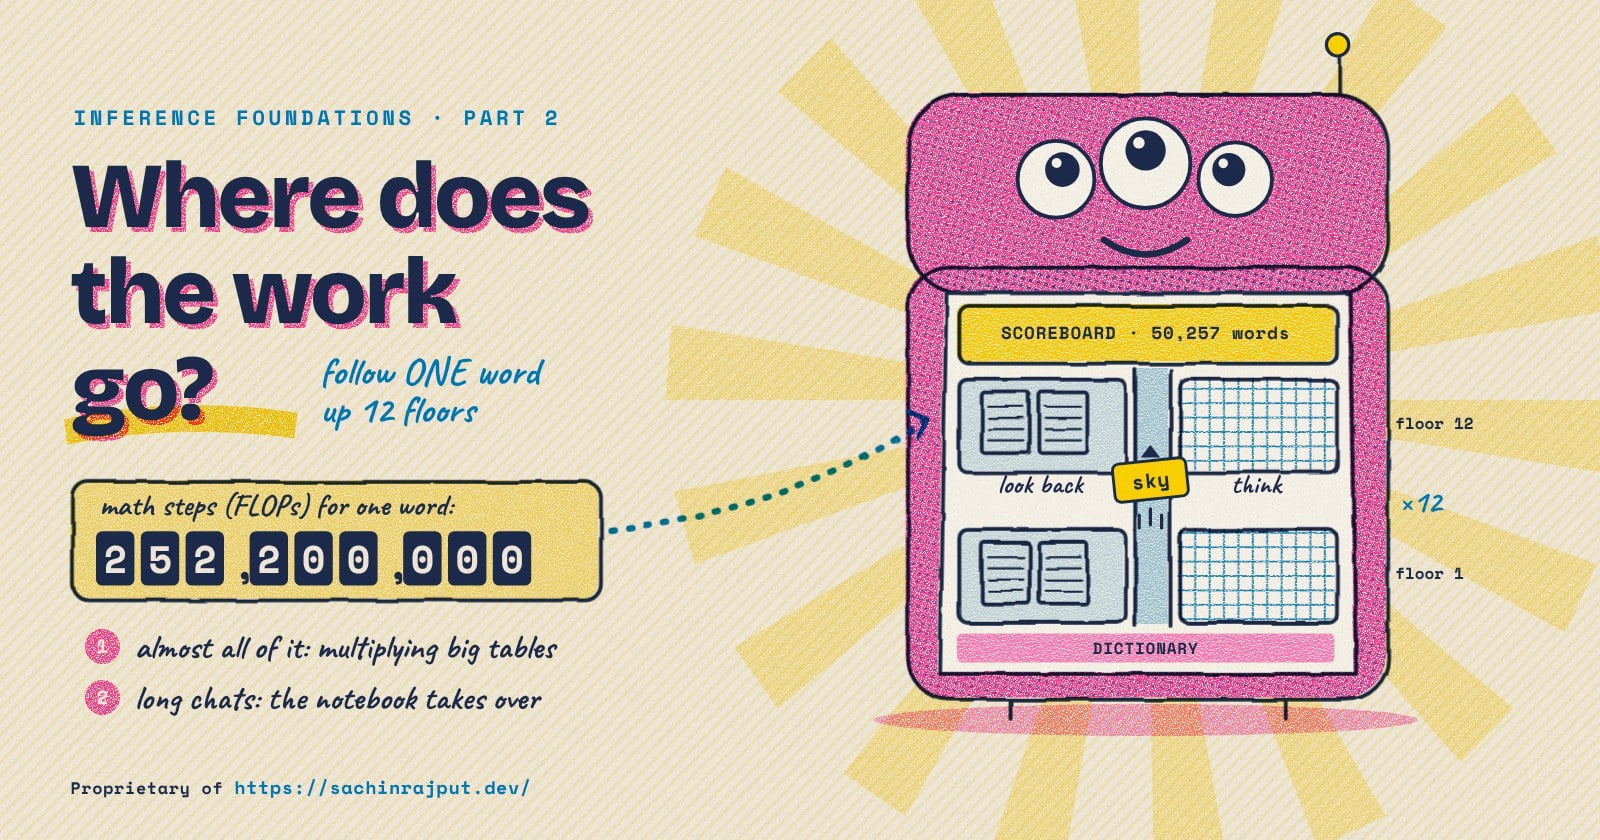
Ride along with one word as it climbs through a language model, and count every bit of math it causes.